ssTitles
Turns screenshots of recommendations into a verified watch list.
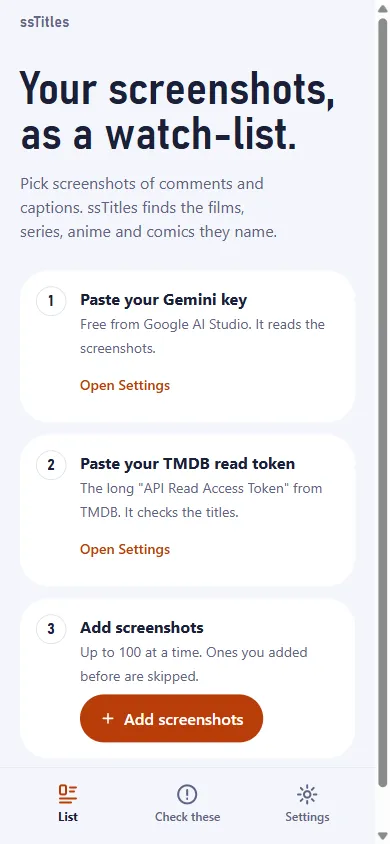
Screenshots of "you have to watch this" comments pile up in the gallery and the titles never get written down. ssTitles reads them with a vision model and gives back a de-duplicated list of the films, series, anime and comics they name, each checked against a real catalogue.
Measured
- wrong titles allowed by the release gate
- 0
- median time per screenshot
- 3.2 s
- decoy screenshots given a title
- 0 / 29
Problem
A vision model will happily invent a title, and its own confidence was always 0.9 to 1.0, so it told me nothing. The app had to be honest about what it doesn't know, work on a free API tier with tight rate limits, and keep people's screenshots private without a backend.
Architecture
- Interface
- Storage
- Model
- External
Everything runs in the browser. Each screenshot is re-encoded at 1280 px with its metadata stripped, queued in IndexedDB, and sent to Gemini with a strict JSON schema. Each candidate title is then searched on TMDB, or on AniList for comics, and ranked by exact title, year and popularity. Anything that doesn't verify cleanly goes to a "Check these" screen instead of the list.
Decisions
Pick the model with a measured spike
On 28 real screenshots, Gemini Flash-Lite found 21 of 21 titles with 0 wrong and rejected 9 of 9 decoys at 3.2 s each. A local model also found 21 but got 2 wrong at 11.2 s, and a larger model failed 27 of 28 calls with 503s.
Verify instead of trusting the model
Every title must match a real TMDB or AniList entry. If the catalogue is unreachable the title is marked unverified, never guessed.
An eval harness as the merge gate
A labelled set of 74 screenshots runs three times per change, and the bar is 95% found, zero wrong and zero decoys with a title. A prompt change that cost two decoys was shelved even though it fixed other cases.
No backend at all
Users paste their own keys, which stay in IndexedDB and never in the bundle. Nothing is stored on a server, so there is nothing to breach and nothing to pay for.
Hard parts
Free-tier rate limits
A throttle of 12 requests a minute, exponential backoff with jitter, a fallback model, and a queue that pauses, resumes and survives a reload. AniList's 30-a-minute limit is paced request by request.
Generalising, not overfitting
Search variants (text before a colon, singular and plural, joined words) lifted the gate from 49 to 52 or more of 54 titles. A separate held-out set of 100 screenshots keeps the score honest.
Untrusted text from images
Model output is parsed against a strict schema and rendered as plain text. The content security policy only allows Gemini, TMDB and AniList, and denies everything else.
Quality
- About 189 test files: unit, eval and Playwright, including offline, install and axe accessibility specs.
- End-to-end tests block every outside origin, so a test can't quietly leak data.
- Local CI with 11 steps, including semgrep, gitleaks and a header check against the live site.